Predictive maintenance uses condition evidence and, where applicable, validated analytical models to inform maintenance decisions. An observation, a diagnosis and a future failure estimate are different outputs. This guide explains the workflow and the questions needed to judge the evidence behind it.
AI-generated editorial illustration; not a customer photograph or product screenshot.
Predictive Maintenance
Definition and Overview
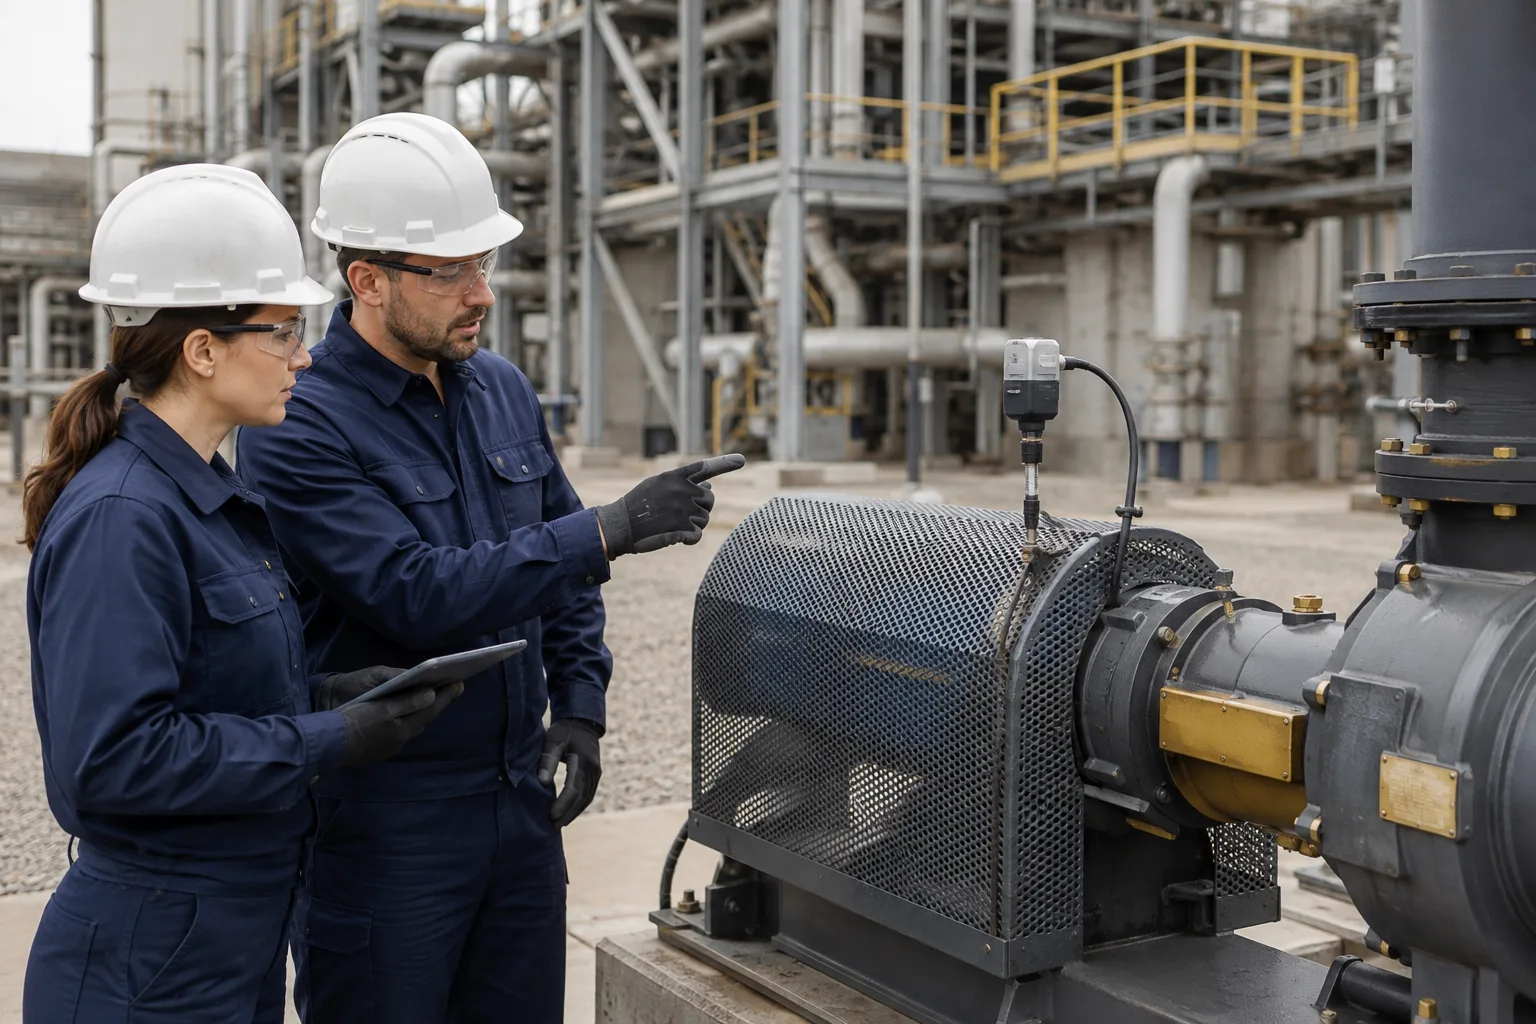
Predictive maintenance (PdM) is a condition-based maintenance strategy that uses data analysis, monitoring technologies, and statistical models to estimate developing condition or failure risk within a defined application. Rather than following fixed maintenance schedules, predictive maintenance uses condition evidence to inform intervention; other approved maintenance tasks may still remain necessary.
The core principle differentiating predictive from preventive maintenance is condition-based intervention. Instead of assuming degradation follows predictable timelines, predictive maintenance monitors actual equipment health through various technologies. Maintenance occurs when condition indicators cross defined thresholds, optimizing timing to prevent failures while avoiding unnecessary interventions.
Predictive maintenance leverages multiple monitoring technologies:
- Vibration analysis detecting bearing wear, misalignment, and imbalance
- Thermography identifying hot spots indicating electrical or mechanical issues
- Ultrasonic testing finding leaks, electrical discharge, and bearing defects
- Oil analysis revealing contamination, wear particles, and lubricant degradation
- Motor circuit analysis assessing electrical equipment health
- Acoustic monitoring detecting abnormal sounds indicating problems
- Performance monitoring tracking efficiency, output, and power consumption
Technologies Used
Effective predictive maintenance relies on sophisticated technologies for data collection, analysis, and decision support:
IoT Sensors and Connected Devices: Modern PdM programs deploy networks of sensors continuously monitoring temperature, vibration, pressure, flow, speed, current, voltage, and countless other parameters. These sensors communicate via industrial networks, providing real-time data streams for analysis.
Industrial IoT (IIoT) platforms aggregate sensor data, apply edge computing for preliminary analysis, and transmit relevant information to central systems. Wireless sensor networks reduce installation costs while enabling monitoring of previously inaccessible equipment.
Condition Monitoring Technologies: Specialized instruments perform detailed equipment assessments:
- Vibration analyzers use accelerometers to detect mechanical problems in rotating equipment. Fast Fourier Transform (FFT) analysis identifies specific defects from vibration signatures.
- Infrared cameras perform thermographic inspections, revealing electrical hot spots, insulation problems, and mechanical friction before visible symptoms appear.
- Ultrasonic detectors identify compressed air leaks, steam trap failures, electrical arcing, and bearing lubrication issues through sound frequency analysis.
- Oil analysis laboratories test lubricant samples for wear metals, contamination, viscosity changes, and additive depletion indicating equipment condition.
Artificial Intelligence and Machine Learning: AI transforms predictive maintenance from reactive diagnostics to proactive prediction:
- Supervised learning algorithms train on historical failure data to recognize patterns preceding breakdowns. Some models estimate remaining useful life or failure probability within a validated application; their uncertainty and failure-mode coverage must be assessed.
- Unsupervised learning identifies anomalies indicating abnormal conditions without requiring labeled failure examples.
- Deep learning processes complex sensor data streams, recognizing subtle patterns humans or traditional algorithms might miss.
- Natural language processing analyzes maintenance notes, operator logs, and technical documents to extract insights complementing sensor data.
Cloud Computing and Edge Analytics: Cloud platforms provide scalable infrastructure for storing vast amounts of sensor data and running computationally intensive analytics. Edge computing performs real-time analysis at or near sensors, enabling immediate responses to critical conditions without cloud latency.
Digital Twins: Virtual replicas of physical assets simulate behavior under various conditions. These models incorporate real-time sensor data, enabling prediction of how equipment will respond to different operating scenarios and maintenance interventions.
CMMS and EAM Integration: Predictive maintenance systems integrate with computerized maintenance management systems (CMMS) and enterprise asset management (EAM) platforms. This integration automatically generates work orders when conditions warrant intervention, tracks actions taken, and closes the feedback loop for continuous improvement.
Mobile Applications: Technicians use mobile devices to receive condition alerts, access equipment history, view sensor trends, and document findings. This real-time connectivity improves response times and data quality.
How Predictive Maintenance Works
Implementing predictive maintenance follows a structured methodology:
Technology Deployment: Install appropriate sensors and monitoring equipment based on failure modes and required data. Consider monitoring frequency (continuous vs periodic), data transmission methods, power requirements, and environmental conditions. Balance monitoring comprehensiveness with cost and complexity.
Baseline Establishment: Collect data from equipment in good operating condition to establish normal performance baselines. These baselines provide reference points for identifying abnormal conditions. Variability in operating conditions requires baselines across different operating modes.
Threshold Development: Define alert and alarm thresholds indicating when conditions warrant attention. Thresholds may use absolute values, deviation from baseline, rate of change, or statistical models. Conservative thresholds generate false alarms while lenient thresholds risk missing developing problems.
Continuous Monitoring and Analysis: Sensors collect ongoing data automatically transmitted to analysis platforms. Software compares current conditions against baselines and thresholds, generating alerts when parameters indicate developing issues.
Alert Management and Diagnosis: When systems generate alerts, qualified personnel review data to confirm legitimate problems versus false positives. Diagnostic analysis determines problem severity, likely causes, and required interventions.
Maintenance Planning and Execution: Confirmed issues trigger maintenance planning. Unlike emergency responses to failures, predictive insights allow scheduled interventions during convenient windows. Technicians prepare necessary parts, tools, and procedures before performing targeted repairs addressing specific problems identified through monitoring.
Model Refinement: Machine learning algorithms automatically improve as they process more data and failure examples. Regular human review ensures models remain accurate as equipment ages and operating conditions evolve.
Benefits Over Preventive Maintenance
Predictive maintenance offers several advantages compared to traditional preventive approaches:
Optimized Maintenance Timing: Preventive maintenance follows fixed schedules that may be too frequent (wasting resources) or too infrequent (missing failures). Predictive maintenance intervenes only when needed based on actual condition, optimizing timing for each specific asset and failure mode.
Targeted Repairs: Preventive maintenance often involves component replacement without understanding actual problems. Predictive diagnostics identify specific defects, enabling targeted repairs that address root causes rather than shotgun approaches that may miss actual issues.
Safety Improvements: Continuous monitoring identifies dangerous conditions like overheating, excessive vibration, or structural degradation before they create hazards. This real-time awareness enhances safety beyond periodic preventive inspections.
Better Resource Planning: Predictive insights provide advance warning of upcoming maintenance needs. This visibility enables better scheduling of labor, ordering of specific parts identified as needed, and coordination with production planning.
Data-Driven Decisions: Predictive maintenance generates extensive performance data supporting continuous improvement. Organizations gain insights into failure patterns, maintenance effectiveness, and asset performance trends that inform strategic decisions about operations, replacements, and investments.
Competitive Advantage: Organizations implementing advanced predictive maintenance achieve higher reliability, lower costs, and better asset utilization than competitors relying on preventive or reactive approaches. This operational excellence translates to market advantages through better pricing, delivery reliability, and resource efficiency.
Implementation Requirements
Successfully deploying predictive maintenance requires significant capabilities and investments:
Technology Infrastructure: PdM demands substantial technology investments including sensors, monitoring equipment, data communication networks, cloud or on-premise computing infrastructure, and analytical software platforms. Initial investments typically range from tens of thousands to millions of dollars depending on facility size and asset complexity.
Technical Expertise: Effective predictive maintenance requires specialized skills often lacking in traditional maintenance organizations:
- Reliability engineers who understand failure mechanisms, monitoring technologies, and analytical techniques
- Data scientists capable of developing and maintaining machine learning models
- Vibration analysts, thermographers, and other condition monitoring specialists
- IT professionals managing sensors, networks, and data infrastructure
- Maintenance technicians trained to interpret condition data and perform precision repairs
Organizations either develop these capabilities internally through training and hiring or partner with service providers offering PdM expertise.
Data Management Capabilities: Predictive maintenance generates vast amounts of data requiring robust management:
- Data collection systems reliably capturing sensor readings without gaps
- Data storage infrastructure handling terabytes of historical information
- Data quality processes ensuring accuracy, completeness, and consistency
- Data integration connecting condition monitoring with CMMS, EAM, and enterprise systems
- Data security protecting sensitive operational information
Organizational Readiness: Cultural and process changes often challenge PdM implementation:
- Leadership commitment to long-term investments with gradual returns
- Cross-functional collaboration between maintenance, operations, engineering, and IT
- Process changes integrating condition insights into work planning and execution
- Acceptance of data-driven decisions rather than experience-based judgment
- Patience recognizing PdM effectiveness improves gradually as models learn
Pilot Approach: Given complexity and investment requirements, successful implementations typically start with pilot programs on selected critical assets. Pilots demonstrate value, develop capabilities, and identify challenges before enterprise-wide deployment.
Vendor Partnerships: Many organizations partner with technology vendors, consultants, or service providers for PdM implementation. These partnerships accelerate deployment, provide access to specialized expertise, and reduce internal capability development requirements.
ROI Analysis
Evaluating predictive maintenance return on investment requires comprehensive cost-benefit analysis:
Long-Term Value: Beyond immediate cost savings, PdM generates strategic value through improved reliability, enhanced safety, better planning capabilities, and competitive advantages. These strategic benefits often exceed quantifiable cost reductions.
Industry Applications
Predictive maintenance delivers results across diverse industries:
For comprehensive implementation guidance, see our Predictive Maintenance Guide.
AI-generated editorial illustration; not a customer photograph or product screenshot.
Predictive Maintenance Explained
Understanding Predictive Maintenance
Predictive maintenance represents the evolution of maintenance strategies from reactive approaches to intelligent, data-driven decision-making. At its core, predictive maintenance uses condition-monitoring tools and techniques to track the real-time performance of equipment during normal operation, analyzing this data to identify patterns that indicate potential failures before they occur.
Unlike traditional maintenance approaches, predictive maintenance doesn't rely on manufacturer recommendations, historical averages, or gut feelings. Instead, it monitors the actual condition of your specific equipment in your unique operating environment, learning normal baseline behaviors and detecting deviations that signal developing problems.
How Predictive Maintenance Works
The predictive maintenance process begins with comprehensive data collection. Sensors installed on equipment continuously measure parameters like vibration, temperature, pressure, acoustic emissions, oil quality, and power consumption. This data flows to analytics platforms where machine learning algorithms analyze it against historical patterns and normal operating conditions.
When the system detects anomalies—such as increasing vibration levels, temperature spikes, or unusual acoustic signatures—it identifies potential failure modes. Advanced algorithms can predict not just that a failure will occur, but what type of failure, which specific component is affected, and approximately when the failure is likely to happen. This intelligence enables maintenance teams to schedule interventions at optimal times with the right parts, tools, and expertise ready.
The Evolution from Preventive to Predictive
The maintenance industry has undergone significant transformation over the past decades. First-generation reactive maintenance gave way to second-generation preventive maintenance in the 1960s and 1970s as equipment became more complex and downtime costs increased. Preventive maintenance improved reliability but couldn't address the inefficiencies of time-based scheduling.
The Role of Data and Analytics
Data forms the foundation of predictive maintenance. Modern predictive maintenance systems can collect thousands of data points per second from individual assets, creating massive datasets that reveal equipment behavior patterns invisible to human observation. This data includes not just sensor readings but also maintenance history, operating conditions, environmental factors, and production schedules.
The power of predictive maintenance lies in its ability to move from descriptive analytics ("What happened?") through diagnostic analytics ("Why did it happen?") to truly predictive capabilities ("What will happen and when?") and ultimately prescriptive guidance ("What should we do about it?").
AI-generated editorial illustration; not a customer photograph or product screenshot.
How Predictive Maintenance Works
Understanding the predictive maintenance workflow helps organizations implement effective programs that deliver promised benefits.
Data Collection Process
Predictive maintenance begins with comprehensive data collection from multiple sources:
Operational data from control systems, SCADA systems, and manufacturing execution systems provides context for sensor readings. Understanding operating speed, load, temperature, and production status helps algorithms distinguish normal variations from actual anomalies.
Maintenance history feeds into predictive models, documenting past failures, repairs, part replacements, and maintenance activities. This historical data helps algorithms learn failure patterns and refine predictions.
Environmental data captures ambient conditions—temperature, humidity, dust levels—that influence equipment performance and degradation rates.
Real-Time Monitoring and Analysis
Once collected, data flows through multiple analysis stages:
Data cleansing removes noise, handles missing values, and validates sensor readings to ensure analysis operates on quality data. Automated quality checks flag sensor malfunctions or data transmission errors.
Baseline establishment determines normal operating parameters for each asset under various conditions. Machine learning algorithms learn that "normal" for a heavily loaded motor differs from "normal" at light loads, establishing dynamic baselines that account for operational variations.
Continuous comparison measures real-time data against established baselines, calculating deviations and trends. Statistical process control techniques identify when measurements exceed expected variation ranges.
Pattern Recognition and Anomaly Detection
Advanced analytics identify meaningful patterns within the data:
Frequency analysis transforms time-domain vibration signals into frequency spectra, revealing characteristic patterns associated with specific mechanical problems. Bearing defect frequencies, gear mesh harmonics, and imbalance signatures become visible through Fourier transformation.
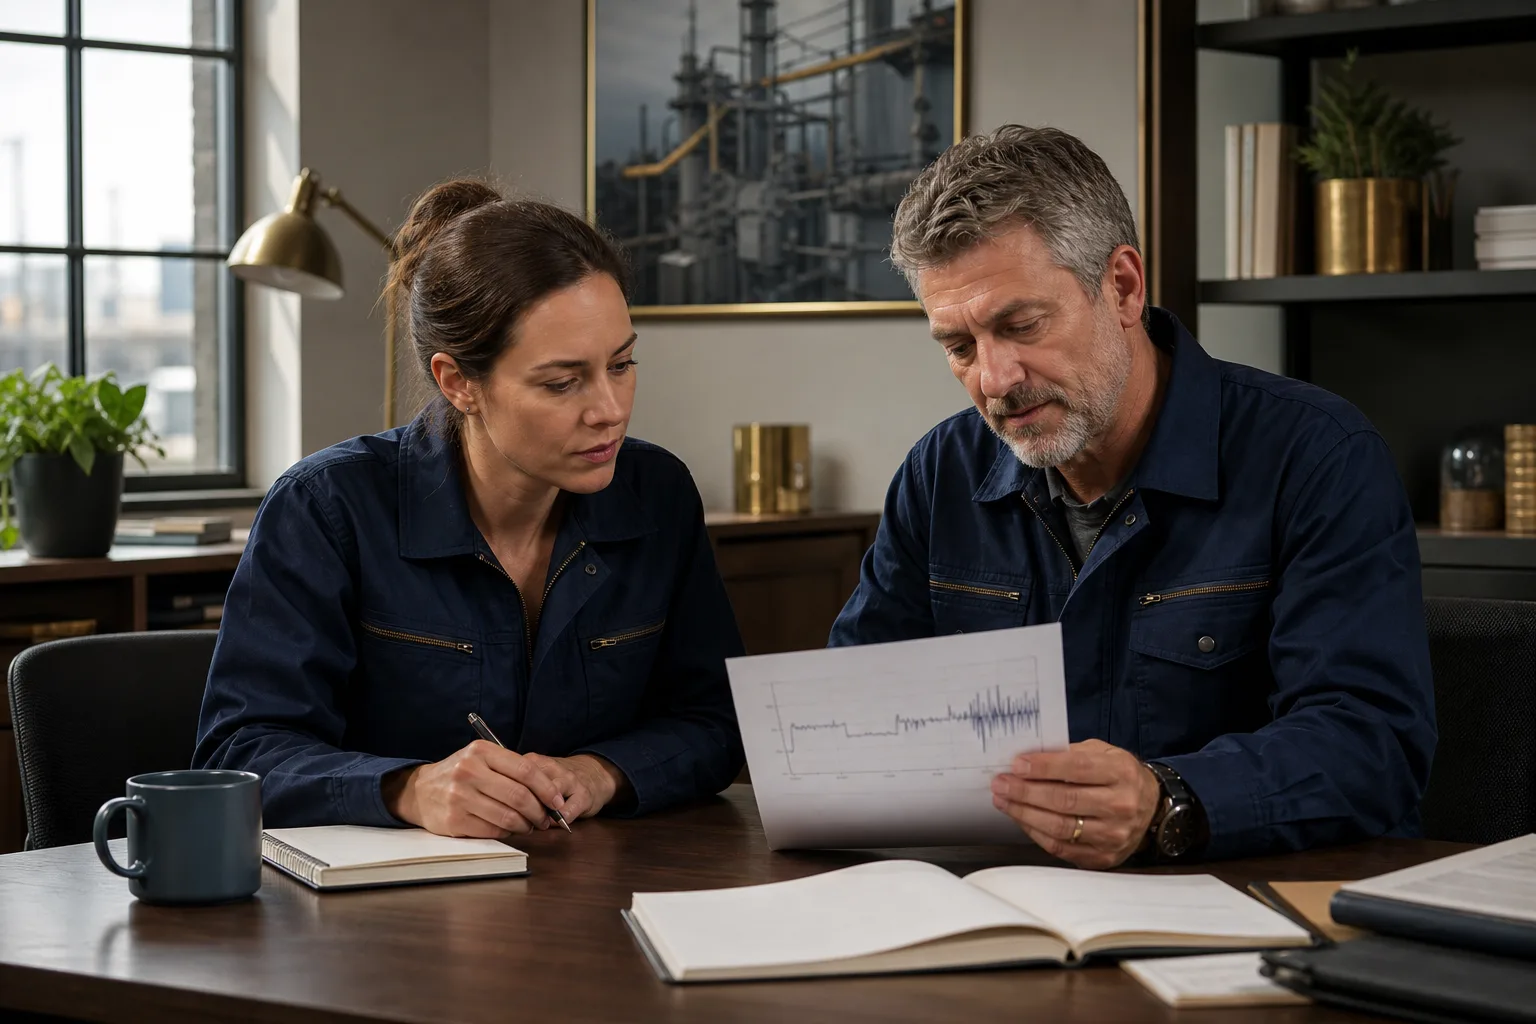
Trend analysis tracks parameters over time, identifying gradual degradation that might not trigger threshold alarms but indicates developing problems. A bearing temperature that slowly increases over weeks signals developing issues even if it remains below alarm thresholds.
Correlation analysis identifies relationships between different parameters. Relationships between signals can support investigation, but correlation alone does not establish a specific failure mode.
Anomaly detection flags unusual patterns that deviate from learned normal behavior, even when the specific anomaly hasn't been previously categorized. An anomaly is a reason for review; it does not by itself identify a novel failure mode or its cause.
Failure Prediction and Remaining Useful Life Estimation
Evaluate the distinct analytical outputs rather than treating every condition alert as a failure prediction:
Failure mode identification determines not just that a problem exists, but specifically what is failing. Vibration frequency analysis might distinguish between outer race bearing damage versus inner race damage, enabling precise diagnosis before visual inspection is possible.
Severity assessment evaluates how advanced the degradation is and how rapidly it's progressing. Early-stage bearing damage might warrant monitoring, while rapidly advancing damage requires immediate intervention.
Remaining useful life (RUL) prediction estimates the time window available before maintenance becomes necessary. RUL estimates enable optimal scheduling, performing maintenance during planned downtime rather than emergency shutdowns.
Confidence levels accompany predictions, indicating the statistical certainty of the assessment. Confidence measures must be interpreted with the model assumptions, consequences and available evidence. The responsible reviewer determines the response through the approved process.
Alert Generation and Prioritization
Effective alerting balances responsiveness with alert fatigue prevention:
Severity-based alerting categorizes issues by urgency—informational notifications for early-stage degradation, warnings for developing problems requiring attention, and critical alerts for imminent failures requiring immediate action.
Multi-channel notifications ensure the right people receive alerts through appropriate channels: dashboard displays for reliability engineers, email for maintenance planners, SMS for critical alerts, and work order generation for scheduling systems.
Alert contextualization provides maintenance teams with not just notification of a problem but comprehensive context: the specific asset, problem type, predicted failure mode, recommended actions, required parts, estimated labor hours, and safety considerations.
Alert suppression prevents duplicate notifications and alert floods during known shutdown periods or when issues are already being addressed.
Maintenance Scheduling and Work Order Generation
Predictive insights drive optimized maintenance execution:
Priority-based scheduling ranks maintenance needs by criticality, failure probability, and remaining useful life, ensuring resources focus on the highest-impact activities.
Coordination with production schedules identifies optimal maintenance windows that minimize production impact, performing predicted maintenance during planned shutdowns rather than forcing unplanned stops.
Resource optimization ensures required parts, tools, and skilled technicians are available when needed, making resource constraints visible before the planned intervention.
Automated work order creation generates maintenance work orders directly from predictive analytics platforms, seamlessly flowing into CMMS systems with comprehensive diagnostic information and recommended procedures.
This integrated workflow transforms predictive maintenance from interesting data into tangible operational improvements, connecting reviewed findings to owned actions and verification.
AI-generated editorial illustration; not a customer photograph or product screenshot.
Separate observation, diagnosis and prediction
A condition observation describes a measured state or change. A diagnosis interprets evidence about a possible cause. A prediction estimates a future outcome within stated assumptions. These are different outputs, and a product that provides one should not automatically be described as providing all three.
For an illustrative example, a reviewed signal may show a change under comparable operating conditions. The team might decide that an inspection is appropriate without claiming a particular component has failed or estimating its remaining life. That can be a useful condition-based decision even when no predictive model is present.
If a supplier offers a remaining-life estimate, ask what event the estimate refers to, which equipment and conditions it covers, and how uncertainty is represented. A precise date on a screen is not evidence of precise knowledge. The responsible technical reviewer should determine whether the output is suitable for the proposed decision.
AI-generated editorial illustration; not a customer photograph or product screenshot.
Evaluate a model without testing on the answer
Ask how the model was developed and evaluated. Historical records used to fit or tune a model should not also be treated as independent evidence that it predicts new cases. The evaluation needs a defensible separation between development information and the observations used to assess performance.
Retain the definition of a positive event, the observation window and the available failure labels. Maintenance history can contain inconsistent names, incomplete diagnoses and interventions that prevent observation of a later failure. Those limitations affect what can be learned or verified from the data.
Review the consequences of false alarms and missed concerns separately. A model that rarely raises an alert may look quiet while missing important events. A model that alerts frequently may create an unsustainable investigation workload. The appropriate tradeoff depends on the application and responsible risk assessment, not a universal accuracy target.
AI-generated editorial illustration; not a customer photograph or product screenshot.
Compare the proposed method with the existing decision process
Use a relevant baseline, such as the current approved inspection route or a simpler reviewed condition rule. The question is whether the proposed method improves the decision enough to justify its extra cost and ownership burden. A more complex model is not automatically a better operational choice.
Include interpretation, data correction and integration support in the comparison. If a specialist must repeatedly repair missing context before an alert becomes usable, that effort belongs in the operating model. Record the work rather than treating it as invisible project support.
Keep technical and commercial acceptance separate. The system may transfer observations correctly while its diagnostic usefulness remains unproven. It may provide useful findings while the proposed subscription or support arrangement is unsuitable. A clear pilot report can state both results without forcing them into a single success label.
Choose the next guide by the decision you need to make
For measurement specification, identity and connectivity, use the IoT sensor guide. For project scope, ownership and evaluation, use the predictive maintenance implementation guide. For production constraints and verification, use the manufacturing pilot guide.
PreventiveHQ can organize the maintenance work that follows a reviewed finding. Its general work records do not establish that a sensor, diagnostic algorithm or predictive model is included. Test the exact supporting workflow and any required specialist integration before making a purchase decision.